Data engineering
Credit data pipeline
Validate before publishing.
20 data quality rules
Personal data engineering project
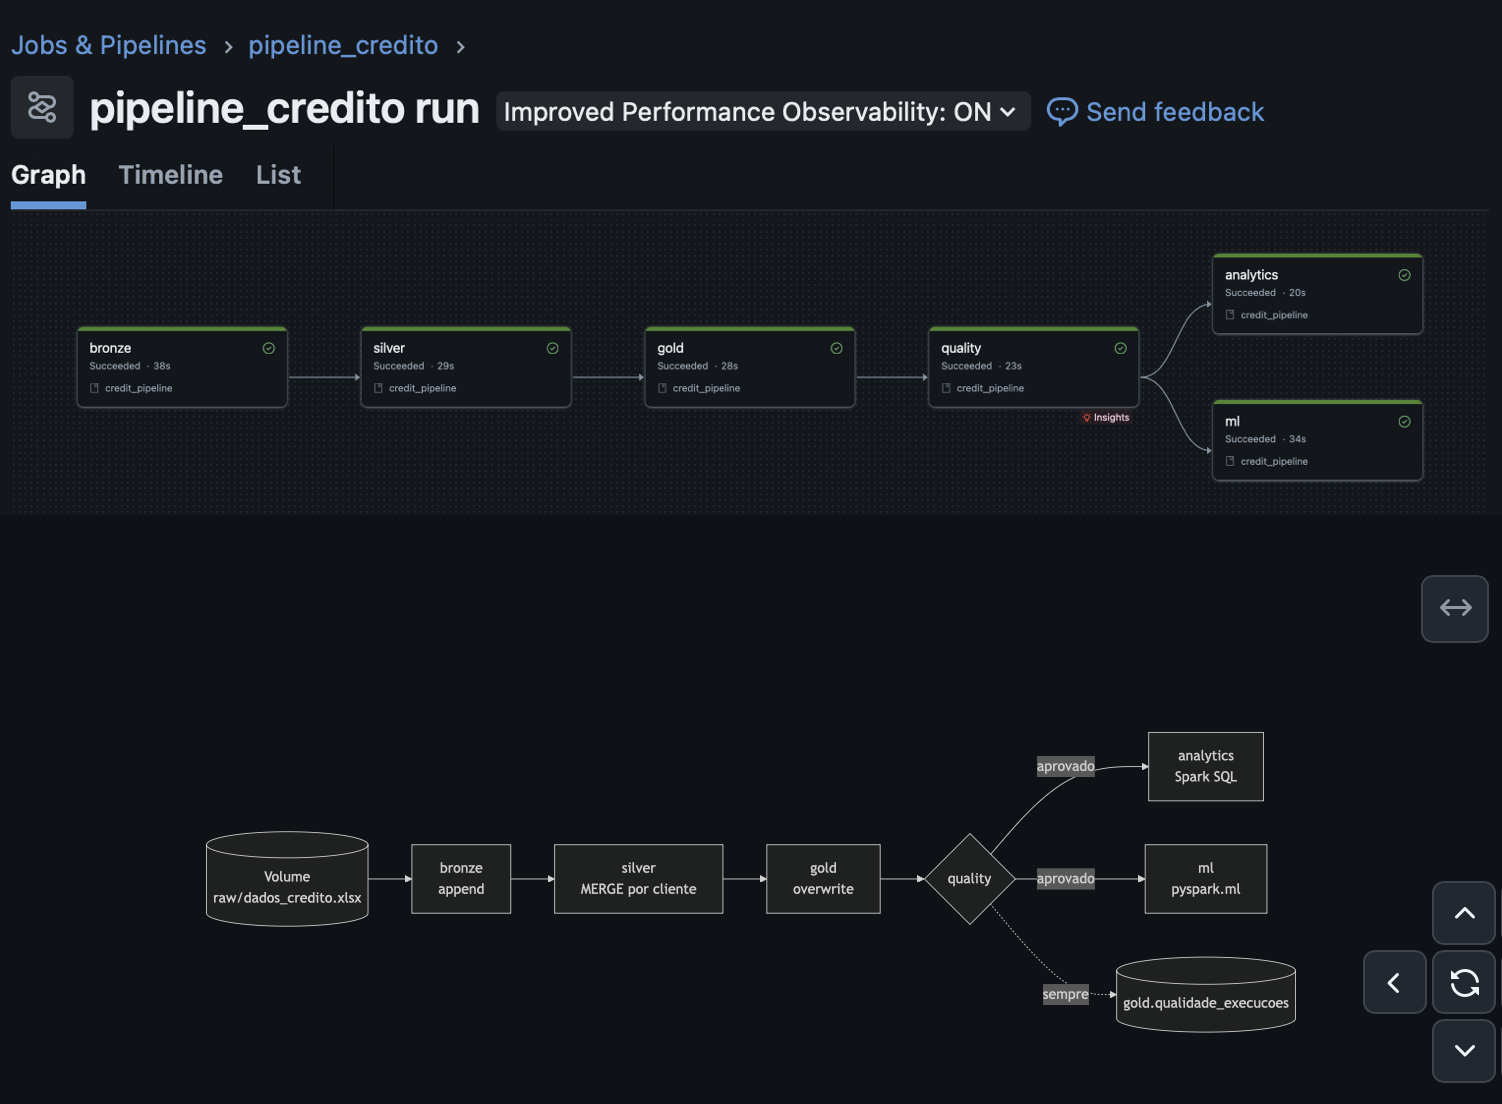
A serverless job with six tasks and over 40 automated tests in the local alternative. It does not represent a lending operation.
THE DECISION THAT MATTERS
Block publication when data fails
A completed run is not enough. Quality rules prevent invalid data from reaching analytics and models, while leaving an audit record.
TRY A PROJECT DECISION
Would you publish this data?
Change the sample and run validation. Publication is allowed only if every check in this demonstration passes.
A local simulation with fictional data and three simplified checks. It does not run Databricks or reproduce the project's 20 rules.
| Customer | Monthly income |
|---|---|
| Customer 101 | R$3,200.00 |
| Customer 102 | R$4,500.00 |
| Customer 103 | R$2,800.00 |
Enable JavaScript to try this out. The project explanation is available below.
The challenge
Credit analytics relies on consistent data. Invalid records should not silently flow into reports and models.
My contribution
I built a Databricks pipeline covering ingestion, processing and data delivery. I included incremental updates, execution auditing and a quality gate with 20 rules.
The result
Data that fails validation blocks publication and subsequent tasks. The same logic also runs locally, with over 40 automated tests.
Personal data engineering project. It does not represent a lending operation or a financial result for clients.
Explore the technical details
Medallion architecture, a six-task serverless job, Databricks Asset Bundles, Delta Lake and Unity Catalog. Bronze with ingestion history and Silver with per-customer MERGE INTO. Quality rules in a single pass, Gold caching and shuffle partition tuning. A local alternative with Parquet, PostgreSQL, Airflow and CI in GitHub Actions.